33 Downloads Updated 4 days ago
Ministral 3 3B Instruct, quantized to Q4_K_M for fast local Ollama inference on Apple Silicon.
ollama run mvincig11/ministral-3-3b-mlx
Models
View all →Readme
Ministral 3 3B Instruct — MLX 4-bit
A compact Q4_K_M quantization of Mistral AI’s Ministral 3 3B Instruct 2512, packaged for fast local inference with Ollama.
Quick start
ollama run mvincig11/ministral-3-3b-mlx
API example
curl http://localhost:11434/api/chat -d '{
  "model": "mvincig11/ministral-3-3b-mlx",
  "messages": [
    {"role": "user", "content": "Explain 4-bit quantization briefly."}
  ],
  "stream": false
}'
Model details
- Base model: Mistral AI Ministral 3 3B Instruct 2512
- Architecture: Mistral 3
- Parameters: 3.4B
- Quantization: Q4_K_M
- Ollama size: approximately 2.1 GB
- Maximum context: 256K tokens
- Default runtime context: 8K tokens
- Input: text
- Capabilities: chat, instruction following, structured output, and tool calling
Benchmark
The same four fixed prompts were run with identical greedy decoding on an Apple Mac mini M4 with 16 GB unified memory. Both the MLX BF16 baseline and the MLX 4-bit model passed all four functional checks.
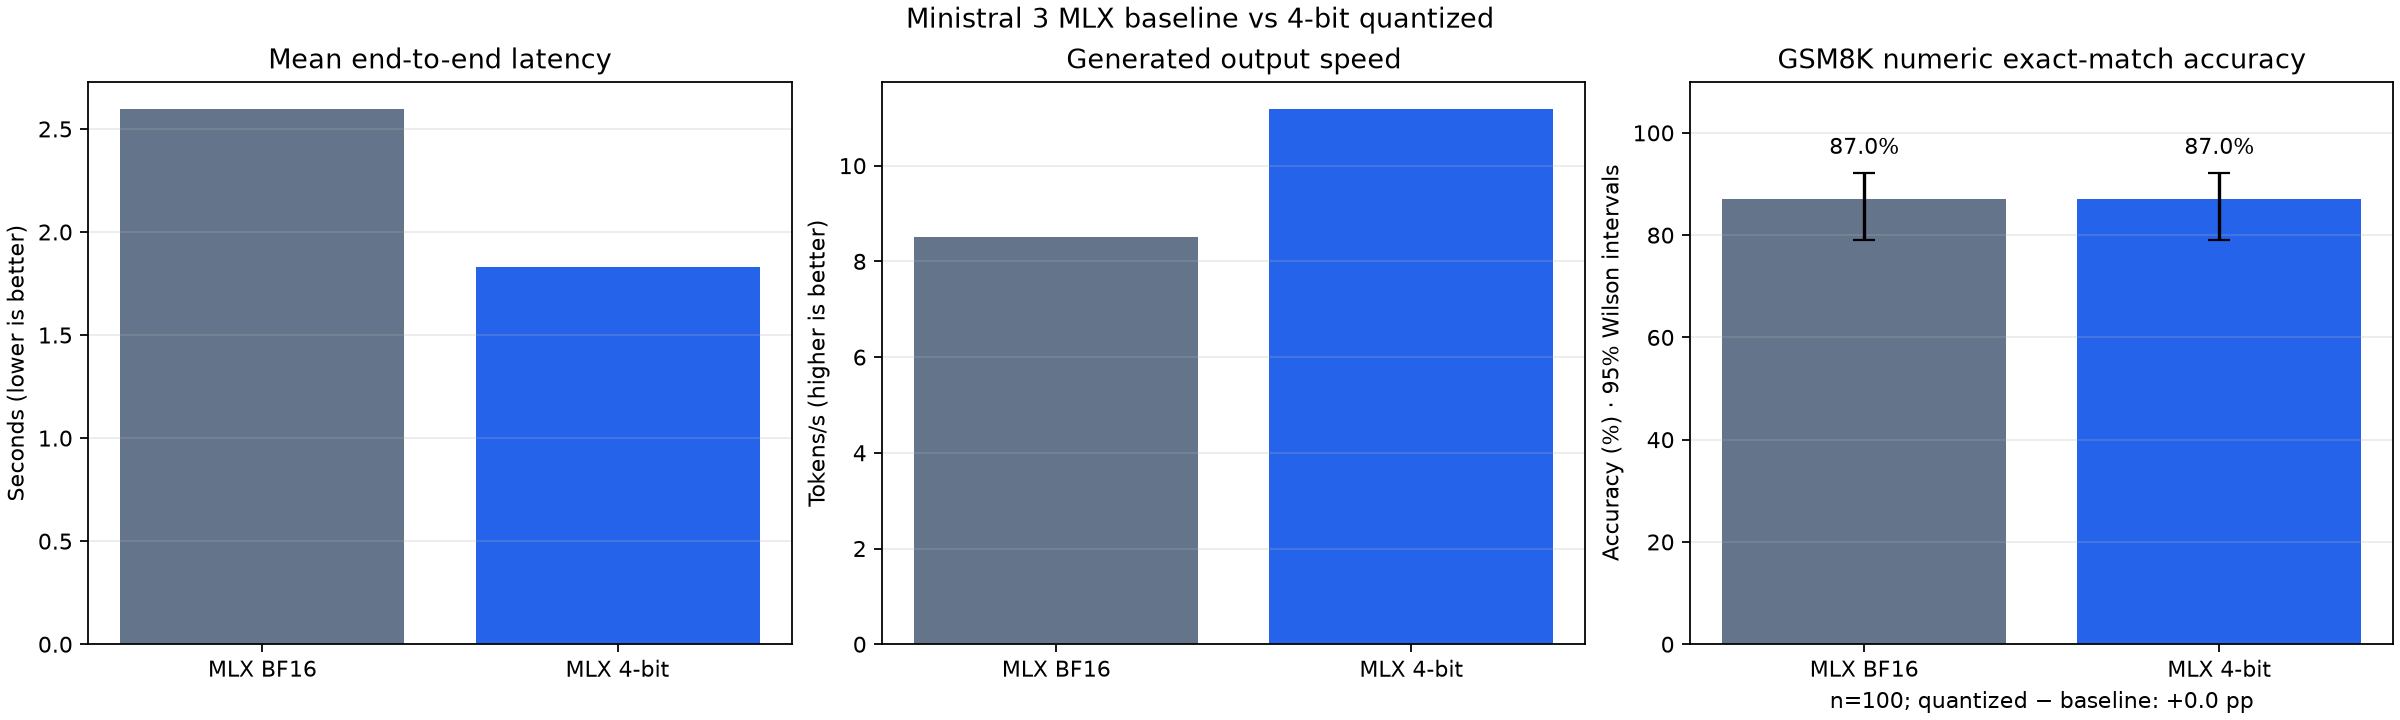
The measured 4-bit run reduced mean end-to-end latency by 37.1% and increased output throughput by 1.92x relative to the measured BF16 baseline.
Results depend on hardware, prompt length, cache state, OS, and runtime version. This is a runtime and functional comparison, not a general quality benchmark, and it does not establish accuracy parity with BF16.
How it was built
The complete reproducible workflow is available in the public repository:
- Source repository
- Conversion notebook
- Repeatable benchmark
- Recorded benchmark results
- Tested dependency lock
The workflow starts from the official Mistral AI BF16 Safetensors checkpoint, converts it to MLX, applies 4-bit affine quantization with group size 64, validates the exported checkpoint, and runs deterministic functional and runtime checks. No fine-tuning or additional training data were used.
Recommended settings
temperature 0
num_ctx 8192
Increase the context only when needed because KV-cache memory grows with sequence length.
Limitations
- Four-bit quantization can affect accuracy, calibration, formatting, and tool use.
- Generated content may be incorrect or biased; verify important outputs.
- Multimodal behavior is not exposed by this Ollama text package.
Upstream model
License and attribution
This derivative follows the Apache 2.0 license and usage terms of the upstream Mistral AI model. Review the upstream model card before production or commercial use. This is an independent community conversion.