5 Downloads Updated 1 week ago
297M llama-style base model trained from scratch. continues text, not chat
ollama run navthings/lilbase:q8_0
Details
Readme
lilbase
a 297m param llama-style base model, trained from scratch on a kaggle tpu v5e-8.
it’s a base model, so it continues text instead of answering questions. give it the start of a sentence, not a question.
ollama run navthings/lilbase "The water cycle begins when"
tags
| tag | size | notes |
|---|---|---|
latest / q8_0 |
379mb | same perplexity as f16 |
q4_k_m |
273mb | ~0.8% higher perplexity, smallest |
f16 |
594mb | unquantized |
the model
gqa, rope, rmsnorm, swiglu. 24 layers, d=1024, 16 query heads, 4 kv heads, 1024 context. llama tokenizer, 32k vocab.
trained on 6.1b tokens of fineweb-edu (sample-10BT). roughly chinchilla-optimal for this size. 11,043 steps of 524k tokens. held-out loss ended up at 2.608 (perplexity 13.6).
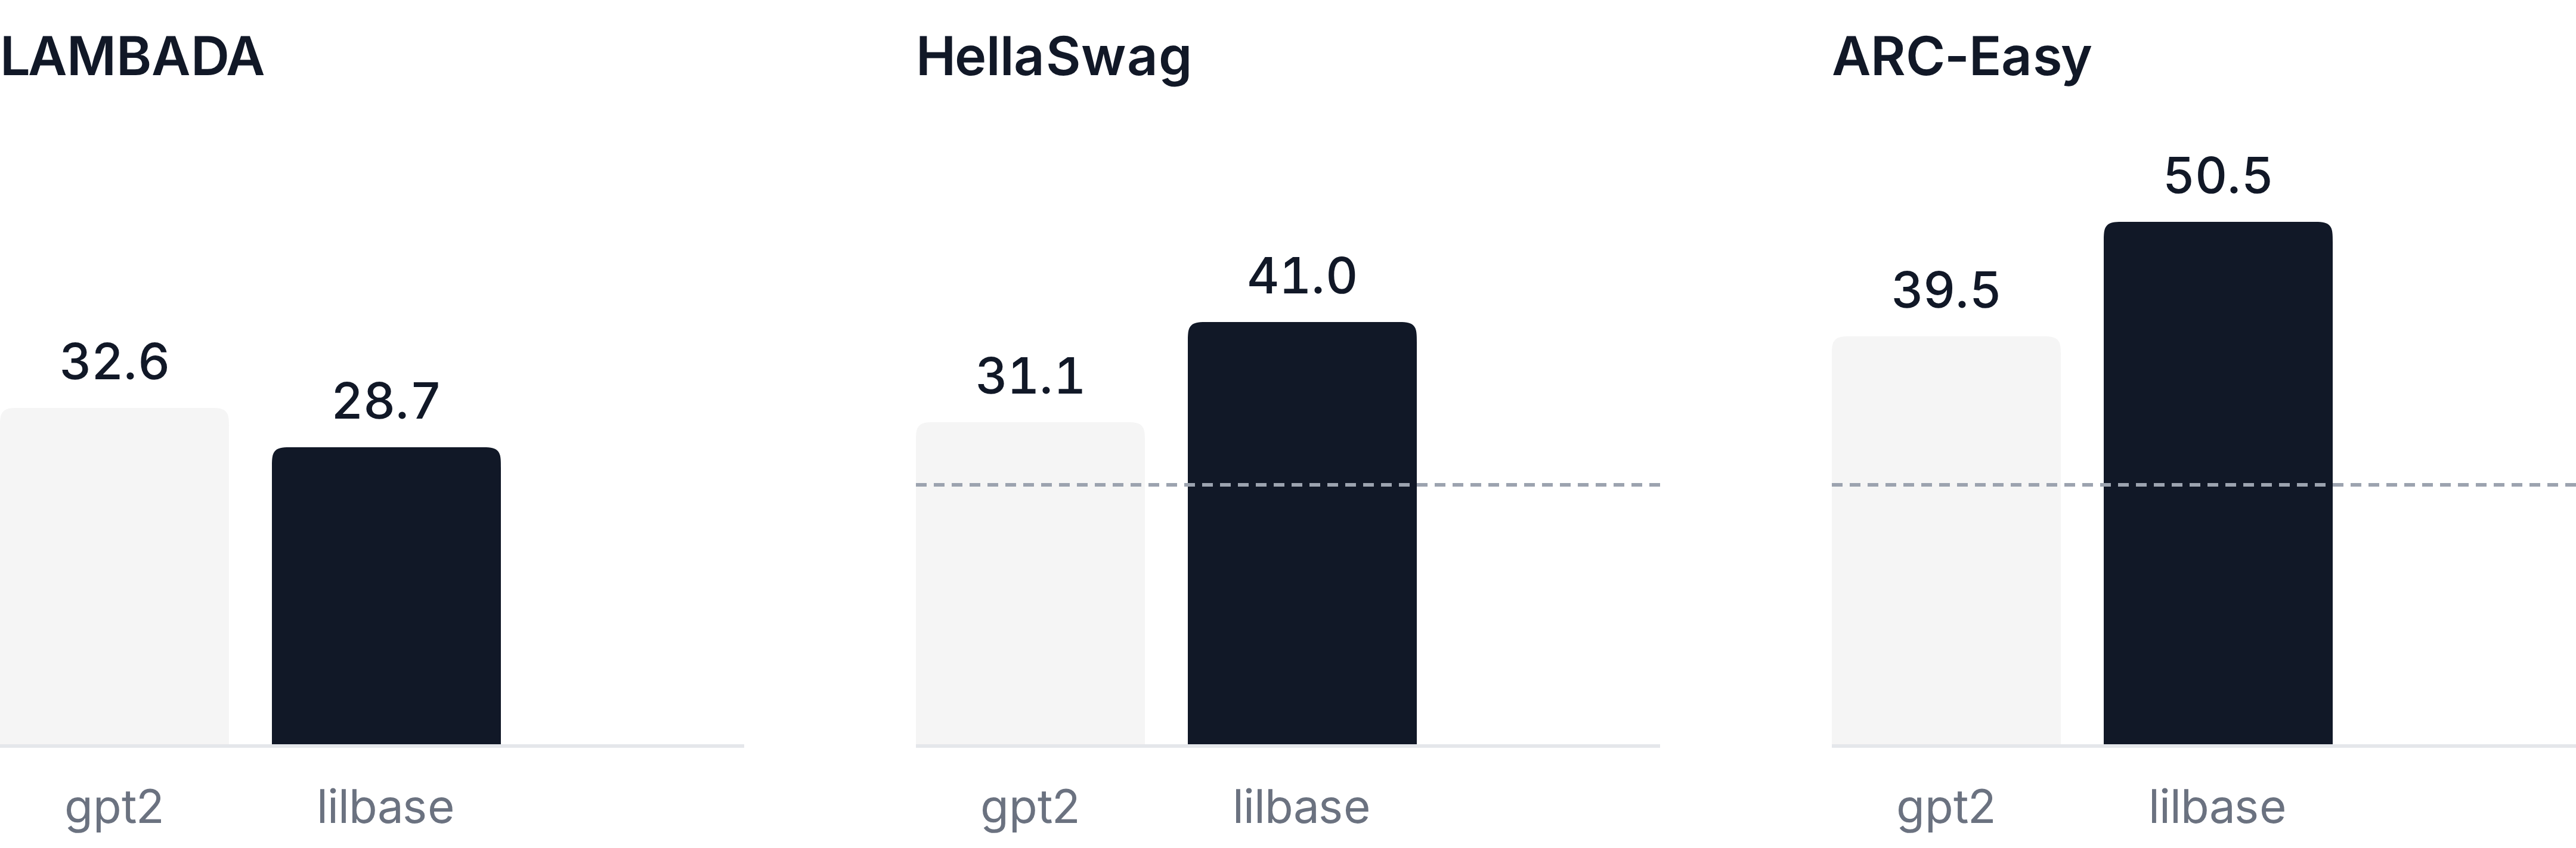
it’s performance against gpt2:
code
https://github.com/navthings/lilbase
kaggle notebook: https://www.kaggle.com/code/navneetdagdiya/base-tpu-kaggle